How BERD@NFDI aims to make business studies data-ready
Ulrich Krieger on new infrastructures for the economic sciences
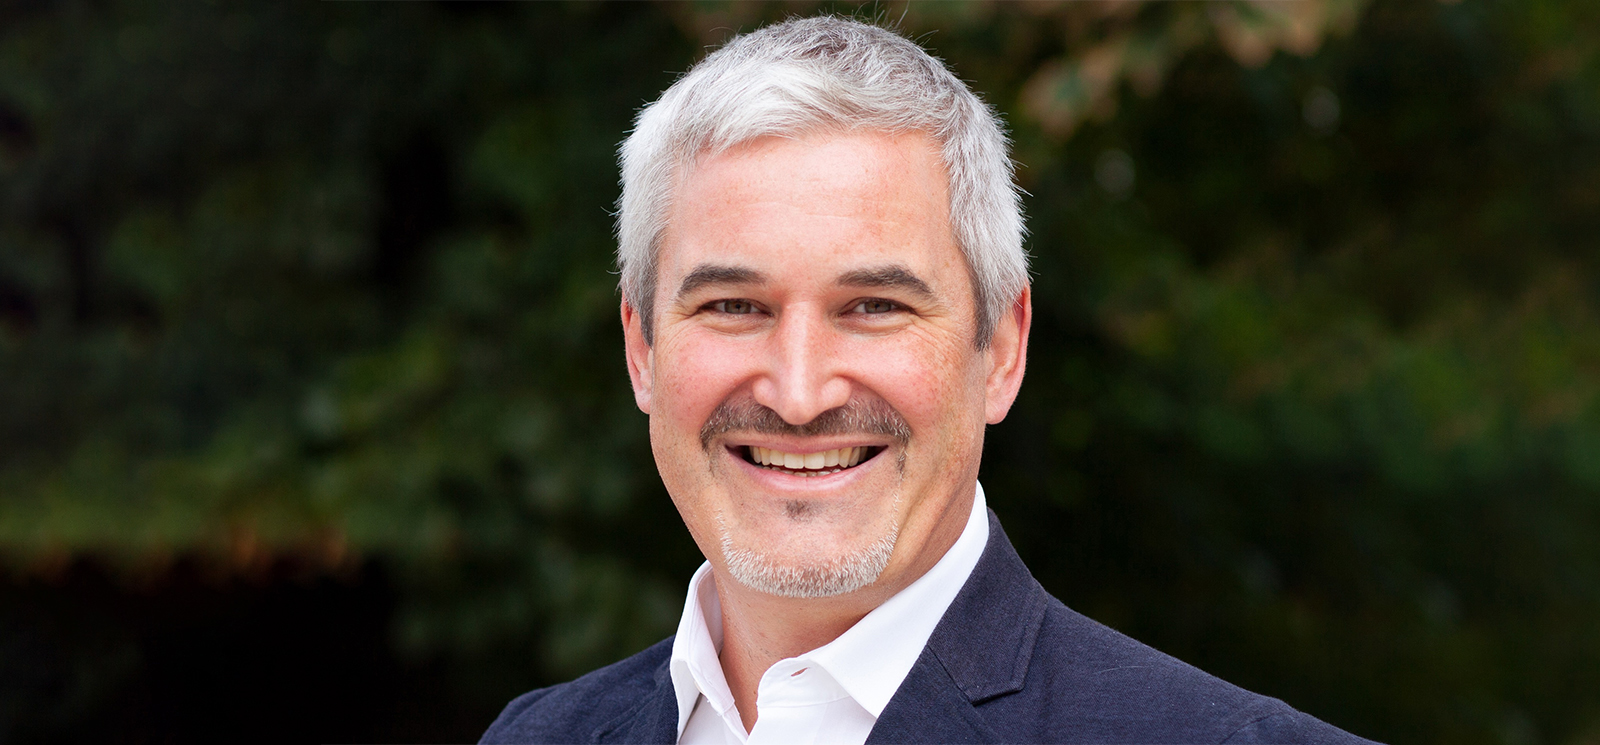
Photo: Kathrin Glückler
The three key learnings:
- Open Science does not necessarily mean that all data must be completely freely available. This is often not possible, particularly in the case of company data, confidential information or proprietary sources. What is crucial is to document data, methods, processing steps and restrictions in such a way that others can understand, verify and, where possible, reuse the research.
- BERD@NFDI combines infrastructure, capacity building and practical research activities. BERD does not merely provide technical services such as repositories or data portals. The consortium combines these services with data stewards, training, methodological support and AI-based tools. This creates an integrated infrastructure that helps researchers find data, document it, use it in a legally compliant manner and make it reusable for others.
- Open Science does not depend solely on the commitment of individual researchers. Reliable repositories, data stewards, training programmes, legal advice and well-integrated research infrastructures are essential. Only such structures make it possible to systematically document, share and reuse data and methods.
What does Open Science mean to you personally? How important is it to you?
UK: For me, Open Science was actually important even before I knew the term. At some point, I realised that I had essentially already been working as a data steward long before it was called that. Sharing data, making it available to others and ensuring the traceability of research – that has always been a matter of course for me.
Towards the end of my degree, I was involved in a graduate survey here at the University of Mannheim. It wasn’t just about collecting data, but also about preparing it in such a way that it could be reused as a resource. Later on, this was also a central theme in various panel studies: designing research in such a way that data remains available in the long term and as many other researchers as possible can work with it.
To be honest, the idea of collecting data just for oneself and then not making it accessible has always seemed rather alien to me. It was only later that I realised that Open Science encompasses much more, such as open publication formats or data literacy. But the fundamental attitude has actually always been there. If you’re conducting research yourself and making something available, it should, as far as possible, also benefit others. And I believe that’s precisely where the benefit lies. Research improves when more people can get involved, contribute their ideas and carry the work forward.
And looking at BERD@NFDI now: what does Open Science mean for the consortium?
UK: Individual aspects of Open Science are very important to us. However, I wouldn’t say that BERD@NFDI is an Open Science consortium in the very broadest sense. For example, we do not deal directly with the topic of Open Access or open publishing. Our focus is more on research data management – that is, on making data understandable, discoverable and easily reusable, and on bringing these issues into the economics communities.
In my view, this is precisely where there is a close connection to the Open Science community. Within the NFDI, we often tend to speak in terms of the FAIR principles. This is also the area in which we are particularly active. And that is why the Open Science Officers and other Open Science stakeholders at the universities are, for us, entirely natural allies. You can sense this time and again in our joint work. So whilst we do not address every aspect of Open Science, we are very deliberately driving forward key elements of it.
The NFDI consortium is now on the verge of transitioning from the set-up phase to the second funding phase. As project coordinator, what is your assessment of the first phase, and which results do you consider particularly sustainable?
UK: We are now on the verge of a decision regarding further funding for BERD. But regardless of that, my assessment of the first phase is positive. I believe we have succeeded in bringing the topic of research data management more firmly into communities for which it has long been far from a given on the agenda. To be fair, it must be said that none of this was entirely new, and there had, of course, already been important groundwork laid previously, including by the ZBW. But I do think that we were able to provide an additional impetus within the field of economics. My impression is that topics such as open science, the reusability of data and data-related infrastructures are currently gaining significant momentum.
If we have helped more people in the economics research communities to recognise this as an important issue and to understand that more needs to be done in this area, then I consider that a great success. And I find it particularly encouraging that, in many fields, there is now a much clearer understanding of just how important data-driven research is. What’s fascinating is that some sub-disciplines have, at their core, long been working in a data-driven way without always reflecting on this so explicitly. I consider the further strengthening of precisely this awareness to be a key achievement of the first funding phase.
Would you say that this is down to BERD? Or is business administration, in its search for new legitimacy, increasingly adopting standards from the natural sciences?
UK: I think both factors have come together here. On the one hand, there is clearly a trend within business studies towards more data-driven research, greater transparency and a stronger interest in issues of reusability. On the other hand, I believe BERD has already helped to raise the profile of these issues and provide them with a concrete framework.
You can now see this in very practical terms at conferences or in working groups. There’s certainly a lot of movement there. I wouldn’t therefore say that BERD initiated all of this on its own. But we have certainly helped to take up this development and carry it forward. And when something like this comes together in the middle – that is, existing dynamics within the academic communities and an initiative such as BERD – then that is actually the very best thing that can happen. For BERD itself, the initial phase naturally involved a great deal of groundwork. A new group of researchers and infrastructure organisations came together in a completely new constellation, whilst at the same time the NFDI as a whole first had to find its feet. In my view, the positive evaluations and the successes to date also demonstrate that this has been achieved successfully. I also think it’s important that we give the economic sciences a voice within the NFDI. After all, it’s not just about individual services, but also about representation, visibility and ensuring that this major area of the research landscape has its rightful place there. And I’m actually very proud of the specific services we’ve set up – that is, applications that directly benefit researchers.
Which one is your favourite?
UK: One of my favourites is definitely the data repository that we set up in collaboration with the ZBW. I consider this so important because, in business studies, research data has often been much harder to find than, for example, in political science or sociology, where large and well-established survey structures have long been in place. In my view, creating greater transparency and facilitating access to data represents real progress. However, I also find the newer AI-supported applications exciting. For example, we are working on systematically indexing content from publications and semi-automatically extracting methodological information – such as details on the use of specific pre-processing methods – from academic articles. Such applications can help make research more transparent and bring methodological developments into sharper focus.
I also think the new service we’ve launched to make scales from business administration research easier to find is excellent. This shows that sometimes even relatively small gaps can pose a major practical hurdle. If such materials have previously only been available in scattered form or in volumes that are difficult to access, the barrier to using them is high. Making this digitally searchable brings immediate benefits. And once we’ve resolved the remaining legal issues, I’ll consider that a real success. And our BERD Academy is, of course, another huge plus. The fact that so many people are taking part and the feedback is so positive clearly shows that there is a genuine need within the community.
When you describe the data portal to the academic community: what problem is it designed to solve, and what is its specific added value?
UK: Our aim is to create a central hub for datasets that are particularly relevant to the field of economics and which have often been difficult to locate until now. In our field in particular, data often appears in connection with publications but is then stored in a very scattered manner – be it on journal servers, on institutional websites or in places where it can only be found with great effort. In some cases, it isn’t even systematically catalogued. This is precisely where we see a real gap. What we want to achieve with the portal, above all, is improved discoverability and greater transparency. Researchers should not have to spend a long time searching for where data is located and in what context it was used; instead, they should have a central point of contact for this. In my view, that is the real added value. At the same time, we also want to use the portal to create an open, freely accessible service – in other words, an infrastructure that is guided by the FAIR principles and is not driven by commercial interests. Researchers should also be able to reliably deposit their own reference data there. So it is not just a matter of making existing data more visible, but also of creating a sustainable and trustworthy environment for the provision and re-use of data.
With the second funding phase of BERD, the focus is shifting more towards consolidation, integration and sustainability. What specific changes will this bring to your work? And how will the business administration community notice that BERD has entered phase two?
UK: In the first phase, we set up, tested and developed many things in different directions. In the second phase, the focus is now more on bringing these services together, integrating them more effectively and making them more reliable overall. For users, this ideally means that services will run more stably, be easier to understand, work better together and be more closely aligned with researchers’ actual needs. So it’s not just a matter of simply continuing with what already exists, but of shaping it into a form that really works in day-to-day use. This includes very practical issues such as stability, performance and user-friendliness – and ultimately, the look and feel of BERD’s services. At the same time, this is not purely an administrative or maintenance phase. Naturally, we also want to carry out targeted further development and incorporate new topics. AI-based applications are a key area in this regard. This involves, for example, the question of how researchers can document their data more easily, provide better evidence of its use, or prepare publications more efficiently. It is precisely such applications that will certainly take on even greater importance in the second phase.
So it’s not just about technical consolidation, but also about creating closer links between the individual services?
UK: Exactly. For us, consolidation always means better interlinking existing services. The aim is for researchers no longer to have to start from many different points, but to come to BERD with a specific research question and then find as much as possible from there. That means data, tools, training programmes and methodological support. This integrated approach is essentially the guiding principle.
At the same time, we have learnt that such integration is not just a technical task, but also an organisational one. In the initial phase, we underestimated the extent of the communication and coordination required – both within BERD itself and in our interactions with the wider NFDI. We are now adapting our structures accordingly, with clearer lines of responsibility and an internal management system designed to function more efficiently. For the business administration community, this may not always be immediately apparent, as much of it happens behind the scenes. But it is precisely this work that is crucial to ensuring the services are sustainable in the long term. And it is also important because we need to link BERD’s services more closely with other NFDI consortia and embed them within the established NFDI. For the business administration community, therefore, phase two should be noticeable above all in that BERD, as an infrastructure, becomes more cohesive, reliable and a natural part of everyday research practice.
When we talk about sustainability and consolidation, the long-term question inevitably arises. What will BERD or the NFDI look like in ten years’ time? And how can such an infrastructure be financed and sustained in the long run?
UK: There is already a fairly clear outlook for the next ten years. The aim is a permanently established national research infrastructure. The individual consortia are expected to be more closely integrated into larger structures, and more services will be operated as joint NFDI services rather than solely as services provided by individual consortia.
And who will fund this in the long term?
UK: In the long term, funding is also to be predominantly public, generally comprising 90 per cent from the federal government and 10 per cent from the federal states. The largest share, at around 80 per cent, is earmarked for the operation of existing services, their stabilisation and work with the communities. A smaller portion, around 20 per cent, is intended specifically to facilitate innovation. At the same time, the NFDI Association will take on a greater role in governance in future. The challenge will lie in achieving greater strategic coordination whilst continuing to closely integrate collaboration with institutions such as the ZBW, GESIS and universities.
Let’s talk about AI. Your website mentions ‘Data4AI’ and ‘AI4Data’. So AI is clearly a key focus. In this context, what do data protection, confidentiality and open science mean? And how, in your view, can the conflict between openness on the one hand and economic interests on the other be resolved?
UK: AI is quite clearly an important issue for us, not only because of its capabilities, but also because of the legal and infrastructural issues associated with it. Particularly when it comes to data protection, confidentiality and copyright, there are real limits that cannot simply be ignored in research. That is why, in my view, it is not just a matter of using the most powerful models available, but of demonstrating how one can work both effectively and in compliance with the law. This is precisely where I see a role for infrastructure organisations. The aim is not to leave researchers to their own devices, but to support them with training, guidance and – and, where necessary, legal support. This is a balancing act, because naturally many researchers initially want to use the most powerful model available.
So your answer suggests that in research, one must not simply use AI, but must also document its use properly. Is that precisely the point where Open Science and the use of commercial all-round AI tools come into conflict?
UK: Yes, that is precisely a key point. Our main aim is to bridge this gap – in other words, to better document which algorithmic methods were actually used and how their use in research can be made transparent. To this end, we want to provide researchers with very specific guidance. One example of this is our new service, Guide-LLM. Essentially, it is a sort of checklist of what should be documented when large language models are used in research. After all, the problem is obvious. Many are already using these systems, but there is often still insufficient transparency regarding exactly what happened, with which settings, and on what basis. Our aim is therefore not necessarily to replace every instance of use with our own models. But we want to help ensure that the use of AI becomes methodologically sounder, more documentable and thus more compatible with scientific standards.
And do you think that is enough to defuse the conflict with open science?
UK: It’s a first step, but of course not the whole solution. It becomes more difficult where traceability and reproducibility depend on other researchers being able to afford the same commercial tools or licences. That’s problematic from an open science perspective. In a way, this is reminiscent of the earlier debate about proprietary and open-source statistical software, except that it has now intensified once again with LLMs. That is why we are also looking into whether self-hosted models can be used in certain areas – partly for copyright reasons, but partly also in the interests of scientific sovereignty. The crucial factor, of course, is whether these models are powerful enough for the purpose in question. If that is the case, it fits much better with an open science approach. Ultimately, it won’t always be possible to fully unpack the black box. But we can and must document its use in such a way that research remains intersubjectively verifiable. And I believe this awareness is now becoming increasingly widespread.
You hinted earlier at how important exchange within the NFDI is. What does this collaboration look like in practice when it comes to AI? Do the consortia develop common approaches, or does this happen on a more ad hoc basis?
UK: As far as collaboration with other consortia is concerned, there is certainly an exchange of ideas. For example, we recently held a major international workshop focusing on the use of LLMs in academic publications. The main focus was on ethical and legal issues – precisely the topics that many consortia are currently grappling with in equal measure. Furthermore, collaboration often arises where we recognise that specialist interests or methodological questions overlap. With consortia that are thematically or methodologically close to us – such as – the exchange is correspondingly closer. In the case of text analysis methods, for example, there are points of contact with other fields that use similar methods and therefore face similar questions. However, I wouldn’t say that there is already such a thing as a uniform, cross-consortium AI strategy within the NFDI. At the moment, these are more like targeted, ad hoc collaborations, where they make sense from a subject-matter perspective and where it becomes apparent that problems or interests actually overlap.
What does the topic of data literacy mean in concrete terms in the context of BERD? And in which areas are you specifically building up skills because you recognise that there are still gaps there?
UK: We are bringing our data literacy programmes together under the umbrella of the BERD Academy. There, we offer programmes for researchers themselves, as well as programmes for multipliers – for example, ‘train-the-trainer’ courses. Our approach is to look very closely at the needs within the communities. What is currently required, what methodological developments are emerging, and where are new requirements arising as a result of technical developments? We then use this to develop programmes that are as concrete and practical as possible. It is important to us that data literacy does not remain merely abstract methodological knowledge, but is closely aligned with research practice. That is why we have also run many hands-on workshops in which researchers have worked with their own data. These were not just about getting to know specific tools, but above all about the practical question of how to make data-driven research transparent. How do I document my steps in such a way that others can understand them and, ideally, replicate them?
Business administration frequently works with corporate data, platform data, unstructured data and, in some cases, confidential datasets. Does this require a specific form of data literacy?
UK: Yes, I would certainly say that business administration presents its own specific challenges. A key challenge is that many people work with proprietary or confidential datasets. This is precisely what makes issues of documentation and traceability significantly more difficult than in fields where data is more standardised or publicly available. Added to this is the fact that access to such data is often organised in a very informal manner, for example through personal contacts with companies that the doctoral supervisor may have established. In practice, of course, this is often the very means by which research becomes possible in the first place. At the same time, however, this raises the all the more pressing question of what sort of dataset this actually is. How can I document it in such a way that my research remains traceable? And how might I find ways to make at least the analysis or a synthesised version of the data accessible without breaching confidentiality?
Does business administration therefore require not only methodological but also specific communicative and collaborative skills when dealing with such data, particularly when access to company data arises through relationships, trust and, often, lengthy initiation processes?
UK: I’m not a business studies scholar myself, but my impression is that access to data is often not the main problem at all. In many cases, there is far more data than can actually be systematically analysed in the end. Access is frequently gained through work placements, collaborations or personal contacts. The real challenge lies rather in dealing professionally with the conditions attached to such data. Anyone working with corporate data must understand that companies have different expectations regarding confidentiality, documentation and use than, say, a research data centre. Companies often do not supply data in a format that is directly geared towards scientific re-use, and they frequently do so with their own interests in mind, be it with regard to visibility, collaboration or potential insights.
Anyone working with corporate data must understand that the mindset there is often very different from that in the traditional scientific data context. The norm is not, at first, that data is shared, but rather the opposite. Data is regarded as sensitive, as business-critical, and possibly also as legally sensitive. The starting point, therefore, is often one of caution. If, despite this, someone within a company decides to grant researchers access, that is a huge step. This requires trust on the part of the company, sometimes courage too, and certainly a certain understanding of how academia works and why such collaborations can be worthwhile. I consider taking this particular dynamic into account to be an important part of data literacy in business studies.
If access to company data often depends on trust and personal openness, shouldn’t we be raising awareness more strongly during business studies that data sharing and scientific collaboration are valuable? So that there are more and more people within companies who can open doors?
UK: Yes, that’s an important point. Essentially, it’s about fostering an understanding early on that points towards open science. When data is available, the first instinct shouldn’t be to share it only within the narrowest academic circle, but to think more broadly and make it accessible for academic collaborations. This certainly represents a cultural shift, which is why the undergraduate stage is so important. I hope that, in future, more students will experience for themselves how helpful it can be when reliable structures are in place for this – for example, via the BERD Data Marketplace, where one can make more targeted contact with companies and initiate collaborations. If such experiences become more common, this could also transform the collaboration between academia and industry in the long term. Not because previous approaches were fundamentally wrong, but because a broader understanding is gradually developing of how data access in research can be organised in a more open and structured way.
If we look at AI once more, it is not only changing tools but potentially the entire research process. What does this mean for data literacy? Is it enough for researchers to learn how to use such systems in practice, or do they also need to understand how these models work, how they are trained, and what their limitations are?
UK: I believe we are really only at the very beginning of a development that will bring about significant change. We can already see that AI not only speeds up individual work processes, but also changes the way research questions are formulated, addressed and translated into text. This makes certain activities accessible to far more people, and that inevitably changes the requirements for data literacy as well.
That is why, in my view, it is not enough simply to learn how to operate such systems. Researchers must also develop a fundamental understanding of how these models work, who provides them, what interests are involved, and what they are capable of – but also, crucially, what they are not capable of. It is precisely this critical aspect that must not be pushed into the background. We can already see just how far this can go. Someone recently told me about an example from computer science where, using agent-based methods, papers were systematically searched for phrases such as ‘more research is necessary’; research gaps were then identified and prioritised, relevant data was sought, hypotheses were formulated, and, on this basis, entire draft papers were produced. On the one hand, this is impressive, but it also demonstrates just how drastically research processes are currently changing.
Would a model based on the division of labour be conceivable in future, in which experienced researchers primarily select relevant questions and hybrid teams comprising AI and academic staff develop studies and publications from them?
UK: I can certainly envisage that for certain types of research. In particular, work that has so far required a great deal of time for data preparation, coding or learning specific methods could become significantly more efficient. In the social sciences, PhD students sometimes spend months or years bringing datasets into a form suitable for analysis. Some of this painstaking work is likely to be eliminated in future.
Would that be a loss for academia?
UK: Not necessarily. In the best-case scenario, this would give researchers more time for the actual scientific work – that is, contextualisation and interpretation. What do the results mean? How can they be placed within a broader context? What implications do they have for other fields of research or for society? Good science is not merely about processing data and applying methods. What is crucial is the ability to interpret findings, recognise connections and ask relevant questions. This work will not become redundant.
Where, then, would the limits of AI’s use lie?
UK: It becomes problematic when we believe we can outsource the very process of gaining knowledge to machines. AI can support researchers with routine tasks, analyses and the structuring of knowledge. However, it does not replace scientific judgement – that is, the decision as to which question is important, how a result should be contextualised and what conclusions can be drawn from it.
You work as an empirical social researcher in the VHB’s Open Science Working Group. What is your personal vision for this working group?
UK: I used to sometimes think that a funding organisation like the DFG simply had to make Open Science mandatory. That would be convenient, but it’s unlikely to happen. That’s why I’d like to start by listening and gaining a better understanding of the problems and reservations that concern researchers in business administration. Even at the last conference, I found it very enlightening to learn about these perspectives, as I myself come from a different academic tradition.
Within the VHB, you’re also something of a bridge-builder between disciplines. Do you see yourself more as a mediator or as someone who deliberately brings a new perspective to the table?
UK: More as a bridge-builder. Through my work at the NFDI, I’m familiar with many disciplines, and the fundamental challenges are more similar than one might initially think. The differences often lie in the details. In business administration, for example, proprietary data and trade secrets play a greater role. In medicine, on the other hand, the focus is often on personal and particularly sensitive data. Nevertheless, the questions are similar across the board: How can data be shared? How do we deal with errors? What incentives do researchers need?
Can the disciplines learn from one another?
UK: Absolutely. However, one shouldn’t idealise any single discipline. In one meeting, for instance, it was suggested that a particular discipline was particularly advanced when it came to open science. At the same time, several colleagues from that very discipline told me that there were significant problems there, for example with the culture of dealing with errors. It would therefore be wrong to say that one discipline has found the solution and the others simply need to adopt it. It makes more sense to compare across disciplinary boundaries, learn from the experiences of others and avoid repeating their mistakes. We won’t be able to avoid making new mistakes entirely – but we can deal with them in a more informed way.
How would you recognise that the VHB’s Open Science Working Group is working successfully?
UK: For me, the key would be the creation of sustainable processes and structures. We shouldn’t expect to make everything completely and perfectly open straight away. It is more important to try things out, learn from them and gradually build on successful approaches. Another criterion for success would be to raise awareness of Open Science within the field of business administration. But what is even more important to me is that the working group does not remain merely a temporary initiative led by a single member of the VHB Executive Board. Open Science should be permanently embedded within the association and continued even through changes in personnel.
Thank you very much!
The interview was conducted on 26 June 2026 by Dr Doreen Siegfried.
This text was translated on 16 September 2026 using DeeplPro.
About Dr Ulrich Krieger:
Dr Ulrich Krieger is Managing Director of the BERD@NFDI consortium at Mannheim University Library. The consortium is developing a research data infrastructure for the economic, social and behavioural sciences, with a particular focus on unstructured data. A social scientist, he has many years’ experience in empirical survey research. In his current work, Krieger combines expertise in survey methodology with research data management and data literacy. Among other things, he explains how research questions, data quality and the FAIR principles interact, and advocates for research practices that are open, traceable and reusable. He is also a member of the VHB’s Open Science Working Group.
Contact: https://www.bib.uni-mannheim.de/ihre-ub/ansprechpersonen/dr-ulrich-krieger/
ORCID.ID: https://orcid.org/0000-0001-6705-7464
LinkedIn: https://www.linkedin.com/in/ulrich-krieger-ma/